What launched
TypeSafe AI released Jev on 15 September 2026 in early access, after about two years in stealth, together with a 40 million dollar seed round led by DCVC. The company calls it the first System One model, a reference to the fast, intuitive thinking in Daniel Kahneman’s Thinking, Fast and Slow, as opposed to slow deliberate reasoning. The model is named after the economist William Stanley Jevons.
TypeSafe was founded in 2024 by Diogo Almeida, Erik Gafni and Sasha Sheng. Almeida, the chief executive, is a former OpenAI researcher and a co-author of the 2022 InstructGPT paper that introduced reinforcement learning from human feedback to a wide audience. Press descriptions of his role in ChatGPT vary, and the architecture of Jev has not been disclosed.
Jev is not open source. There are no published weights; it is used through TypeSafe’s API, with Python and JavaScript SDKs. The stable version is jev-1.13, and jev-1.14 became available as a preview on 14 October 2026. It is also not a rival to general models such as GPT, Claude or Gemini: it is meant to sit next to them.
What it does differently
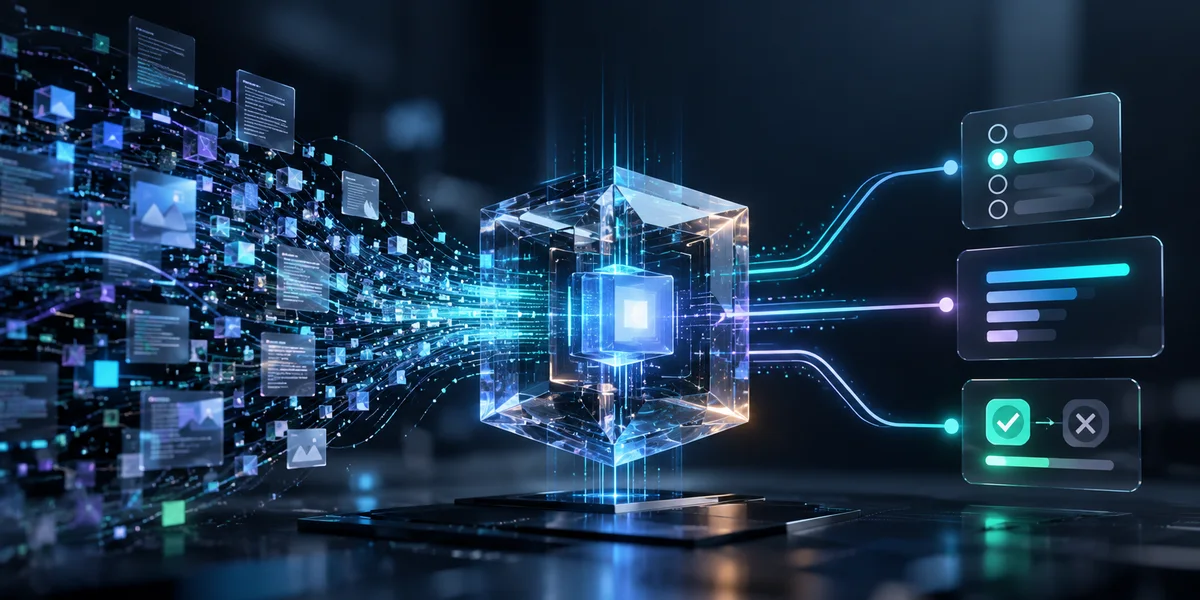
The company’s own summary is: unstructured state in, typed probabilistic decisions out. You define the possible outputs and their structure in advance, and the model answers inside that schema. It cannot produce free-form text, code or prose.
Two design choices follow from that. First, generation is not sequential: instead of one token at a time, all outputs for a request are produced in a single parallel query. Second, every answer carries calibrated probabilities and confidence scores, which the company trains for with a method it calls Reinforcement Learning for Calibrated Decisions. TypeSafe says the model cannot hallucinate and never makes type errors. Read that claim precisely: schema conformance is guaranteed by construction, not measured, and the company states plainly that Jev can still be wrong, which is what the confidence score is for.
How a Jev call works
A request has two parts: the state, which is your data as text or JSON, and one or more questions. There are three question types. Choice picks one option from a fixed list, Score places the state on an ordered scale such as severity, and Noul returns the probability that a statement is true. All questions in a request are answered in parallel and in isolation against the same state, so a question that depends on another answer needs a second request.
A support desk might send a ticket as the state with three questions: a Choice between billing, technical and sales, a Score for urgency from low to critical, and a Noul asking whether the customer threatens to cancel. The answer comes back as three probability distributions, with a confidence for the first two, and code routes on them directly. TypeSafe’s documentation advises asking one narrow question at a time and combining the answers in code rather than asking for a judgment that weighs several factors.
The limits are modest: text input only, 64,000 tokens per request and 32,000 for the state plus any single question.
The numbers, and who produced them
End-to-end response times are quoted as 70 to 500 milliseconds, against 3 to 329 seconds for frontier models on the benchmark site the company cites. Pricing is 0.042 dollars per million input tokens, with output tokens free.
The speed and cost multiples need care. The company claims 40 to 200 times faster at comparable quality on this class of query, and its workflow evaluations report 193.6 times faster and 444.6 times cheaper. Those evaluations were built by TypeSafe’s own team, the reference answers are averaged from two frontier models, and the company itself lists the biases: the workflows are outside Jev’s training distribution, the demo inputs are short in a way that favors Jev, some comparisons ran competitors without reasoning enabled, and it cannot prove its pricing is not subsidized. Treat the ranges as vendor claims with unusually honest footnotes.
What developers reported in the first week
TechCrunch spoke to early users on 18 September 2026, and their reports are more informative than the benchmarks:
- Vercel had been running a classifier that reviews commands for safety on a frontier model. After switching to Jev, an engineer reported results 5 to 18 times more quickly and with greater accuracy.
- Bryo AI tested it against a frontier model for classifying business emails. The frontier model was slightly more accurate, but 10 to 20 times more expensive, and the CTO valued getting back a real probability rather than a word.
- The sharpest caveat came from Armin Ronacher, who pointed out that the design delegates part of the hallucination problem to the user: someone has to decide what a 50% score means versus a 95% one, and act accordingly.
- Demand was high enough that the company temporarily lost the ability to serve its API.
What independent tests found
Independent numbers appeared within days. They are less flattering than the launch charts and more useful.
- On a 2,000-email phishing test, analyst Rajesh Beri found that Jev, asked the single question is this phishing?, scored 62.6% against 81.3% for Claude Haiku 4.5. Split into five narrow questions, such as whether links point to shortened URLs, and combined with a logistic regression fitted on 1,000 labeled emails, Jev reached 95.0% against 93.2% for Haiku built the same way, at 0.038 dollars per 1,000 emails. His conclusion: the accuracy came from how the decision was built, and the probabilities needed calibrating per question.
- InfoQ reported an analysis of 12,759 launch tweets that put the median speedup users saw at 7 times, against the 193.6 times headline, and the median cost saving at 30 times.
- TypeSafe’s own list of jagged edges for jev-1.13 is a good map of where not to use it: literal reading of instructions, arithmetic, date and time comparison, references that need several hops, large state full of irrelevant detail, adversarial content, contradictory criteria, sensitivity to the order of options, and any kind of generation. The advice is to keep math and dates in code, filter the state before sending it, and test edge cases before deploying.
Why the shape matters more than the vendor
Whether Jev specifically wins is beside the point, and within a month it had company. Cloudflare released two open-weight decision models, Clef and Clef-flash, on 1 October 2026 under an Apache 2.0 license, built on frozen Qwen models and described as fully compatible with Jev’s API, which answers the question of whether this kind of model can be self-hosted. OpenAI released a Decisions API in beta on 6 October 2026, built on GPT-6 Luna, which turns text and images into typed answers.
The interesting part is the category: a model that is cheap and fast enough to put a decision inside ordinary control flow, like a smart if-statement, and that returns a number you can threshold instead of a sentence you have to parse.
That opens up a class of work that is currently priced out. Scoring every item on a line rather than a sample. Checking every agent action against a policy before it executes. Judging every generated answer before it reaches a customer. Running a classifier over a million historical records to build a feature, rather than over a thousand to build a slide. The economics of per-item AI change when a decision costs a fraction of a cent and arrives in 100 milliseconds.
It also fits the two-tier pattern that keeps appearing in serious systems: a fast model decides and guards, a slower reasoning model handles the few cases that need deliberation. NVIDIA Research made the same argument from a different direction in its 2025 position paper on small language models in agentic systems: call several right-sized models rather than one large one.
What this means in practice
If you run AI in production, there is a cheap audit worth doing this quarter: count how many of your model calls return something that is really a label, a score or a yes-no, and how much each of those calls costs in money and latency. In most stacks we see, the majority of calls are decisions wearing a chat interface, and they are the first candidates to move to a smaller specialized model. Before you move one, run the new model in shadow mode beside the current one on a log of decisions whose right answers you know.
Then decide what you do with a probability, because that is the actual engineering work. A calibrated score is only useful if you have set thresholds, defined what happens in the uncertain band, and decided who gets the escalation. That is the same discipline we build into agentic automation and into inspection: the model gives a confidence, the system decides automatically where it is confident, and a person decides where it is not. The AIRE engine is built around that split, and models like this one make the fast half cheaper.
 Any questions? Let's talk!
 Write to us,